Monday, June 09, 2014

A declaration of independence (kind of), and technology-induced disintermediation

Musings on the SoCG move to declare independence of the ACM. 

It's a little odd to be sitting in Denmark while high quality rød pølse (with remoulade!) is being made across the world in Kyoto. There's an abysmal lack of blogging/tweeting/facebooking/instagramming/snapchatting/can-I-stop-now-ing from the conference.

Of course following in the lines of the complexity conference, we're attempting to declare our own independence from the EEVVIIL SKELETOR AND HIS MINIONS ACM. Jeff Erickson, our esteeemed grand poobah steering committee chair has put out a series of posts outlining the issues at hand, the history of the matter, and the current status of discussions with SIGACT and ACM. Please visit http://makingsocg.wordpress.com to read, discuss and/or heckle as you see fit.

It might be obvious, but this new wave of devolution is being driven largely by technology - most importantly the existence of LIPIcs. Having a platform for open-access publication with minimal costs exposes as false the claims of institutional providers that they alone can provide the support needed for conferences. In fact, there are a number of related claims that appear to be not true in practice (or at least are not as obviously true as once thought).

* We need the imprimatur of an institutional provider as a signalling mechanism for quality. While it might be too soon to tell if dropping affiliation with established institutions (IEEE or ACM) will affect how publications in a venue will be perceived, there's a lot of confidence in the communities that their long-established reputation will outweigh any loss of prestige.

* Institutional providers provide quality editorial and archival services necessary for a serious venue. I think juxtaposing 'quality' and 'editorial' together with Sheridan Printing might cause my two remaining readers to die of hysterical laughter. But the archival issue is a good one. LIPIcs appears to be funded solidly by the German government for a while, and will take a fixed fee from a conference for publication (capped at 750 €). But the Arxiv was struggling for a while. Should we view the ACM and IEEE as "more likely to last" than any other entity ?

* Institutional providers provide the backing and clout needed for conference organization, hotel bookings and so on. This is another good example of a time-money tradeoff. Organizations like SIAM actually do take over the management of the conference: while the results are not always optimal, there is a clear reduction in hassle for the conference organizers. But organizations like the ACM don't take things over in the same way (and from what I can tell, neither does IEEE). I'm surprised though that there aren't yet lean-and-mean event planning providers that we can just pay money to and make our planning problems go away.

* Institutional providers have the financial wherewithal to manage cycles in revenue streams for a conference. This is another real issue. Conferences that have gone independent have eventually managed to maintain a steady income stream, but theory conferencs are smaller and poorer: it remains to be seen whether we can generate the kind of endowment needed to insulate the community against the natural variation in revenue from year to year.

What's disappointing is that none of this had to play out this way.

  • Take LIPICs for example: they clearly marked out their scope -- indexing, archiving functions and hosting -- while staying away from the more content-driven aspects of the process (editing, proofing etc). This makes a lot of sense, given that everyone who publishes knows how to use LaTeX and style files, but might still not be able to make a web page. Why couldn't the ACM have realized this and provided a slimmed-down publishing service ? 
  • Why do we go to Microsoft (or Easychair, or hotCRP, or Shai Halevi's software) for our conference submission servers ? If the ACM had provided a service of this kind (or even provided hosting for hotCRP/Shai's software), we'd be happily using it right now, and it could have then tied nicely into Regonline, that ACM already partners with. 
  • A lot of the current angst seems to have tone as a root cause: a certain feeling about the provider's attitude towards the conference. This is again something that could have been recognized and addressed before things got to this stage. 
While it's exciting to be part of the "academic spring" (?), people tend to forget that in all revolutions someone gets hurt, and often things don't get better for a long time. I'm intrigued by our attempt to move towards independence though, and the people involved have thought this through very carefully. 


Tuesday, May 20, 2014

On beauty and truth in science.

Philip Ball writes a thought-provoking article in Aeon with the thesis that the kind of beauty that scientists describe does not necessarily match the aesthetic notions of art, and is not even consistent among scientists.

It was hard for me to get beyond the casual conflating of beauty in mathematics (the four-color theorem, the proof of Fermat's theorem, and proofs in general) and beauty in scientific theories (relativity, evolution, and so on). But if one goes beyond the artificial duality constructed by the author, the idea of beauty as a driver in science (and mathematics) is a rich one to explore.
A particular example: for a long time (and even codified in books) it was taught that there were five natural classes of approximation hardness: PTAS, constant factor-hard, log-hard, label-cover (superlogarithmic) hard, and near-linear hard. There were even canonical members of each class. 

Of course, this nice classification no longer exists. There are even problems that are $\log^* n$-hard to approximate, and can also be approximated to that factor. And to be fair, I'm not sure how strong the belief was to begin with. 

But it was such a beautiful idea. 

At least in mathematics, the search for the beautiful result can be quite fruitful. It spurs us on to find better, simpler proofs, or even new ideas that connect many different proofs together. That notion of connection doesn't appear to be captured in the article above: that beauty can arise from the way a concept ties disparate areas together. 

MADALGO Summer School on Learning At Scale

I'm pleased to announce that this year's MADALGO summer school (continuing a long line of summer programs on various topics in TCS) will be on algorithms and learning. The formal announcement is below, and registration information will be posted shortly. 

Save the date ! Aug 11-14, 2014.
MADALGO Summer School on 
LEARNING AT SCALE
   August 11- 14, 2014, Aarhus University, Denmark

OVERVIEW AND GOAL
The MADALGO Summer School 2014 will introduce attendees to the latest developments in learning at scale. The topics will include high dimensional inference,  algorithmic perspectives on learning and optimization, and challenges in learning with huge data. 
LECTURES
The school will be taught by experts in learning:
  • Amr Ahmed (Google)
  • Mikhail Belkin (Ohio State)
  • Stefanie Jegelka (Berkeley)
  • Ankur Moitra (MIT)
PARTICIPATION
The summer school will take place on August 11-14, 2014 at Center for Massive Data Algorithmics (MADALGO) at the Department of Computer Science, Aarhus University, Denmark. The school is targeted at graduate students, as well as researchers interested in an in-depth introduction to Learning. Registration will open soon at the school webpage. Registration is free on a first-come-first serve basis - handouts, coffee breaks, lunches and a dinner will be provided by MADALGO and Aarhus University. 
ORGANIZING COMMITTEE
  • Suresh Venkatasubramanian (University of Utah)
  • Peyman Afshani (MADALGO, Aarhus University)
  • Lars Arge (MADALGO, Aarhus University)
  • Gerth S. Brodal (MADALGO, Aarhus University)
  • Kasper Green Larsen (MADALGO, Aarhus University)
LOCAL ARRANGEMENTS
  • Trine Ji Holmgaard (MADALGO, Aarhus University)
  • Katrine Østergaard Rasmussen (MADALGO, Aarhus University)
ABOUT MADALGO 
Center for Massive Data Algorithmics is a major basic research center funded by the Danish National Research Foundation. The center is located at the Department of Computer Science, Aarhus University, Denmark, but also includes researchers at CSAIL, Massachusetts Institute of Technology in the US, and at the Max Planck Institute for Informatics and at Frankfurt University in Germany. The center covers all areas of the design, analysis and implementation of algorithms and data structures for processing massive data (interpreted broadly to cover computations where data is large compared to the computational resources), but with a main focus on I/O-efficient, cache-oblivious and data stream algorithms.

Thursday, May 01, 2014

The history of the vector space model

Gerald Salton is generally credited with the invention of the vector space model: the idea that we could represent a document as a vector of keywords and use things like cosine similarity and dimensionality reduction to compare documents and represent them.

But the path to this modern interpretation was a lot twistier than one might think. David Dubin wrote an article in 2004 titled 'The Most Influential Paper Gerard Salton Never Wrote'. In it, he points out that most citations that refer to the vector space model refer to a paper that doesn't actually exist (hence the title). Taking that as a starting point, he then traces the lineage of the ideas in Salton's work.

The discoveries he makes are quite interesting. Among them,

  • Salton's original conception of the vector space model was "operational" rather than mathematical. In other words, his earliest work really uses 'vector space' to describe a collection of tuples, each representing a document. In fact, the earliest terminology used was the 'vector processing model'. 
  • In later papers, he did talk about things like orthogonality and independence, as well as taking cosines for similarity, but this was done in an intuitive, rather than formal manner. 
  • It was only after a series of critiques in the mid 80s that researchers (Salton included) started being more direct in their use of the vector space model, with all its attendant algebraic properties. 
Of course today the vector space model is one of the first things we learn when doing any kind of data analysis. But it's interesting to see that it didn't start as this obvious mathematical representation (that I've taken to calling the reverse Descartes trick). 

Wednesday, April 30, 2014

SIAM Data Mining 2014: On differential privacy

After my trip to Haverford, I attended the SIAM Data Mining (SDM) conference in Philly. For those who aren't that familiar with the data mining universe, SDM is the SIAM entrant in the data mining conference sweepstakes, along with ACM (KDD) and IEEE (ICDM). SDM is probably also the smallest of the three venues, which makes it comparable in feel to SODA (also because of SIAM organization). The conference attracts the usual data mining suspects, but also more of the applied math folks.

I was the tutorials chair this year, and there were a number of very well-attended tutorials ranging from applications to core mining to theory. In particular, +Moritz Hardt and +Aleksandar Nikolov did a very nice tutorial on differential privacy entitled 'Safer Data Mining'.


SDM is a good venue for theory folks wanting to "test the waters" with data mining: the papers are consistently more mathematically oriented and less "business-heavy", and it's a friendly crowd :).

Shameless plug: I'm the PC co-chair next year along with Jieping Ye and I'd encourage more algorithms folks to submit, and visit Vancouver in April.

In a future post I'll talk more about a panel I also ran at the conference titled 'Ethics in Data Mining'

Tuesday, April 22, 2014

The Shape of Information

A brief synopsis of my general-audience talk at Haverford College. 

I'm currently visiting Haverford College at the invitation of +Sorelle Friedler as part of Haverford's big data lecture series. Today's talk was a general audience talk about data mining, titled 'The Shape Of Information': (GDrive link)
The Shape Of Information 
What makes data mining so powerful, and so ubiquitous? How can the same set of techniques identify patients at risk for a rare genetic disorder, consumers most likely to like Beyonce's latest album, or even a new star from an sky survey ?  
The answer starts with an idea Descartes had nearly 500 years ago. He suggested expressing geometry in terms of numbers (coordinates). This turned out to be a powerful technique that led (among other things) to the development of the calculus. Data mining returns the favor. It starts with sets of numbers that describe a collection of objects. To find patterns in these objects, we create a geometry in which the numbers are coordinates. And just like that, objects become shapes, and the search for information becomes a quest for common structure in these shapes. 
In this search, we are not limited by the geometry of our world: we can dream up ever more intricate geometries that capture the shape of the information that we seek to find in our data. In this sense, data mining is the best kind of science fiction come to life: we craft a world out of our imagination, and let the laws of this world lead us to fascinating discoveries about the data that inhabits it.
I had a great time visiting with Sorelle's students in their data mining class. Haverford College continues to impress me with the quality of their undergrads (and their faculty !)

Friday, April 18, 2014

danah boyd, Randall Munro, and netizens.

danah boyd, author of 'It's Complicated' just gave a tech talk at Google. Her book has been in the news a lot lately, so I'll skip the details (although Facebook ought to be at least slightly worried).

But what I enjoyed the most about her talk was the feeling that I was listening to a true netizen: someone who lives and breathes on the internet, understands (and has helped build) modern technology extremely well (she is a computer scientist as well as an ethnographer), and is able to deliver a subtle and nuanced perspective on the role and use of technology amidst all the technobabble (I'm looking at you, BIG data) that inundates us.

And she delivers a message that's original and "nontrivial". Both about how teens use and interact with social media, and about how we as a society process technological trends and put them in context of our lives. Her discussion of context collapse was enlightening: apart from explaining why weddings are such fraught experiences (better with alcohol!) it helped me understand incidences of cognitive frisson in my own interactions.

What she shares with Randall Munro in my mind is the ability to speak unselfconsciously and natively in a way that rings true for those of us who inhabit the world of tech, and yet articulate things that we might have felt, but are unable to put into words ourselves. Of course they're wildly different in so many other ways, but in this respect they are like ambassadors of the new world we live in.

Thursday, April 17, 2014

STOC 2014 announcement.

Howard Karloff writes in to remind everyone that the STOC 2014 early registration deadline is coming up soon (Apr 30 !). Please make sure to register early and often (ok maybe not the last part). There will be tutorials ! workshops ! posters ! papers ! and an off-off-Broadway production of Let It Go, a tragicomic musical about Dick Lipton's doomed effort to stop working on proving P = NP.

At least a constant fraction of the above statements are true.

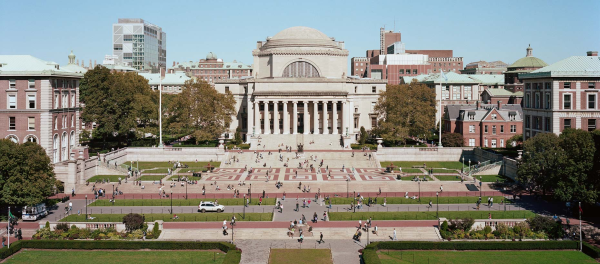
And if you are still unconvinced, here's a picture of Columbia University, where the workshops and tutorials will take place:


Monday, April 07, 2014

Directed isoperimetry and Bregman divergences.

A new cell probe lower bound for Bregman near neighbor search via directed hypercontractivity. 

Amirali Abdullah and I have been pondering Bregman divergences for a while now. You can read all about them in my previous post on the topic. While they generalize Euclidean geometry in some nice ways, they are also quite nasty. The most important nastiness that they exhibit is asymmetry:
\[ D_\phi(x, y) \ne D_\phi(y, x)\]
What's worse is that this asymmetry can grow without bound. In particular, we can quantify the degree of asymmetry by the parameter $\mu$:
\[ \mu = \max_{x,y \in \Delta} \frac{D_\phi(x,y)}{D_\phi(y,x)} \]
where $\Delta$ is the domain of interest.

There's been a ton of work on clustering Bregman divergences, and our work on low-dimensional approximate nearest neighbor search. In almost all these results, $\mu$ shows up in the various resources (space and/or time), and it seems hard to get rid of it without making other assumptions.

After our low-D ANN result, we started trying to work on the high-dimensional version, and our thoughts turned to locality-sensitive hashing. After struggling for a while to get something that might be useful, we started pondering lower bounds. In particular, it seemed clear that the worse $\mu$ was, the harder it became to design an algorithm. So could we actually come up with a lower bound that depended on $\mu$ ?

Our first result was via a reduction from the Hamming cube (and $\ell_1$ near neighbors). While these gave us the desired lower bound, it wasn't $\mu$-sensitive. So we went looking for something stronger.

And that's where isoperimetry made an entrance. There's been a long line of results that prove lower bounds for LSH-like data structures for near neighbor search. Roughly speaking, they work in the following manner:

  1. Construct a gap distribution: a distribution over inputs and queries such that a query point is very close to its nearest neighbor and very far from any other point in the space. In the $\ell_1$ case, what you want is something like $\epsilon d$ distance to the nearest neighbor, and $\Omega(d)$ distance to the second nearest neighbor. 
  2. Imagine your data structure to be a function over the Hamming cube (assigning blocks of points to cells) and look at what happens when you perturb it (formally, by defining the function value to be its average over all nearby points)
  3. Use isoperimetry (or hypercontractivity) to argue that the function "expands" a lot. What this implies is that points get scattered everywhere, and so any particular cell you probe doesn't have enough information to determine where the true nearest neighbor actually is. This last step can be proved in different ways, either using Fourier methods, or via the use of Poincaré-type inequalities.

Our initial hope was to use this framework to prove our bound, while incorporating terms relating to the asymmetry of Bregman divergences more directly.

This turned out to be hard. The asymmetry destroys many of the nice algebraic properties associated with the noise operator and related inner products. There's even a deeper problem: if you think of an asymmetric noise operator as pushing things "forward" on a cube with one probability and backwards with another, then it's not hard to imagine a scenario where applying it actually ends up concentrating the mass of the function in a smaller region (which would break hypercontractivity).

We needed two things: a way to get around this not-so-small issue that hypercontractivity isn't true in a directed setting, and a way to analyze the asymmetric noise operator. It turned out that we could circumvent the first problem: we could restrict the class of hash functions we considered in a way that didn't significantly change their entropy (only a constant). Alternatively, we could view hypercontractivity as being true "on average".

The second problem was a bit harder. The solution we came up with was to try and link the directed noise operator to a symmetric operator on a biased space. The intuition here was that the directed operator was creating a nonuniform distribution, so maybe starting off with one might give us what we need.

This actually worked ! There are versions of the Bonami-Beckner inequality in biased spaces that look almost just like their counterparts in uniform space (you merely set the probability of a bit being 1 to $p \ne 1/2$, and the Fourier coefficients are defined in terms of $p$).

There was lots more to address even after the isoperimetry result, but you'll have to read the paper for that :).

I should note that in many ways, this was a "Simons baby": Amir visited during one of the workshops for the program on real analysis, and we had fruitful conversations with Elchanan Mossel and Nathan Keller in early stages of this work.                                                                                                               


Thursday, March 20, 2014

Data Mining, machine learning and statistics.

How does one tell data mining, machine learning and statistics apart ?

If you spend enough time wandering the increasingly crowded landscape of Big Data-istan, you'll come across the warring tribes of Datamine, MachLearn and Stat, whose constant bickering will make you think fondly of the People's front of Judea:


Cosma Shalizi has what I think is a useful delineation of the three tribes that isn't prejudicial to any of them ("Stats is just inefficient learning !", "MachLearn is just the reinvention of statistics!" "DataMine is a series of hacks!"). It goes something like this:

  • Data mining is the art of finding patterns in data.
  • Statistics is the mathematical science associated with drawing reliable inferences from noisy data
  • Machine learning is [the branch of computer science] that develops technology for automated inference (his original characterization was as a branch of engineering).
I like this characterization because it emphasizes the different focus: data mining is driven by applications, machine learning by algorithms, and statistics by mathematical foundations. 

This is not to say that the foci don't overlap: there's a lot of algorithm design in data mining and plenty of mathematics in ML. And of course applied stats work is an art as much as a science. 

But the primary driving force is captured well. 

Wednesday, March 19, 2014

Reproducibility in data mining/learning

Is reproducibility in data mining/learning different from reproducibility in systems research ?

+John Regehr and +Shriram Krishnamurthi have discussions (John, Shriram) arising from a new paper on  reproducibility in computer systems research from people at the U. of Arizona. You should read their posts/G+ discussions for the specifics.

But it got me thinking: is there anything intrinsically different about reproducibility in my neck of the woods ? Many concerns are shared:

  • The need for a standard computing environment to build and test code: MATLAB and scikit-learn make that a lot easier for us: we don't need to worry too much about details of the computing environment/hardware just to get the code to run. 
  • Discrepancies between what is stated in the paper and what the code actually does: that's a problem with any experimental work: John in fact mentions one such issue in one of his recent papers.
  • Code rot: otherwise known as 'graduation' :). I think if more people used public repos like github from the beginning, some of these problem might go away. I would be remiss if I didn't also plug +Robert Ricci's new system AptLab for helping distribute research.
But here's one that may not be shared: data preparation.

It's no secret that data preparation takes most of the time in a data mining pipeline. This includes
  • data cleaning (removing errors, reformatting data)
  • feature engineering (deciding how to truncate, modify or retain certain features)
  • training (cross-validation levels, what data is used for model building and so on)
As with any of the above, a proper specification can ensure true reproducibility, but there are lots of things we might do to data without necessarily even realizing it (if there are bugs in the transformation pipeline) or without thinking we need to mention it (truncating ranges, defining null values away). 

Feature engineering can also be a problem, especially with models that use many features (for example, deep learning systems have lots of "knobs" to tune, and they can be quite sensitive to the knobs).

So one thing I often look for when reviewing such papers is sensitivity: how well can the authors demonstrate robustness with respect to the parameter/algorithm choices. If they can, then I feel much more confident that the result is real and is not just an artifact of a random collection of knob settings combined with twirling around and around holding one's nose and scratching one's ear. 


Tuesday, March 11, 2014

A short not-review of the first episode of Cosmos

If you've been living on a rogue planet wandering through the far reaches of the Local group, you may not have heard of the Cosmos reboot on FOX with Neil deGrasse Tyson.

We finally got around to seeing the first episode yesterday. I was nervous because I loved the original so much and hoped that my kids would like it as well (as all parents know, you can't show fear or the sharks will smell it :)).

Things I liked:

  • The homage to Carl Sagan was done beautifully. If you're going to reboot a franchise, you don't have to pretend that nothing existed before, you know. 
  • The mix of CG + real person and animation was a good way to tell the different stories. I was a little worried about the denouement of the Giordano Bruno tale because my six-year old was watching, but it was done without being too graphic. 
  • The graphics were non-cheesy: but then I wasn't ever worried about the quality of graphics in the original. I'm pretty sure that 20 years from now these graphics will look cheesy as well. The year-long calendar of the universe was a fantastic demonstration of the immensity of time. 
Things I could live without:

Granted, it's the first episode, so there's no point in being too harsh. But 
  • If I had any heartstrings ever, they've been pulled out of shape into long strands of spaghetti. The constant sweeping orchestral background made me feel like I was watching NBC's coverage of the Winter Olympics. I almost expected to see a personal profile of how the universe overcame the adversity of the Big Bang to become the star performer it is today. 
  • As with all modern American shows purporting to be about science, I found the balance between sweeping rhetoric and actual facts to be disturbingly skewed towards the soaring fluffy. Watch some David Attenborough, people ! or even, I don't know, COSMOS itself. But see below...
Overall:
I liked it. No question that I'm watching it again. And the eight-year old loved it ! Thought it was full of information. So maybe my assessment of graphics-to-information ratio is completely off. 

The funniest thing: when it was over, this happened:
Kids: "Let's see the next episode now!"
Me: We'll have to wait a week for it.
Kids: "What do you mean, we have to wait a week ?"
Netflix should be proud. Binge watching on demand is now the default mode. 

Tuesday, March 04, 2014

Two big data talks at Haverford College

I'm giving two talks at Haverford College just before SDM 2014 in Philadelphia. If you're in the area. stop by and say hello !


Thursday, February 06, 2014

On "reverse engineering" algorithms, contextual readings, and the invisible choices that add value to research.

tl;dr: Understanding the value in a piece of work (a paper, an algorithm, a system) is not just a matter of understanding the various parts and how they fit. It is also a matter of understanding why the problem is decomposed that way. This observation has implications for how we read, write and evaluate research. 

Nick Seaver is an cultural anthropologist at UC Irvine.  He just wrote an article at Medium on reverse engineering algorithms. In it he distinguished between the factual reconstruction of an algorithm ("how does it work") from a more probing examination of the way it was designed ("why it is broken down in a particular way").

He comes to a conclusion that is quite sound and not at all controversial:
I want to suggest here that, while reverse engineering might be a useful strategy for figuring out how an existing technology works, it is less useful for telling us how it came to work that way. Because reverse engineering starts from a finished technical object, it misses the accidents that happened along the way — the abandoned paths, the unusual stories behind features that made it to release, moments of interpretation, arbitrary choice, and failure. Decisions that seemed rather uncertain and subjective as they were being made come to appear necessary in retrospect. Engineering looks a lot different in reverse.
But along the way, he makes an insightful observation about the very idea of structuralism as applied to algorithm design: namely, the idea that by breaking down the parts of the algorithm and understanding the pieces and how they fit together we can "understand" the algorithm at some higher level.
When you break an object down into its parts and put it back together again, you have not simply copied it — you’ve made something new. A movie’s set of microtags, no matter how fine-grained, is not the same thing as the movie. It is, as Barthes writes, a “directed, interested simulacrum” of the movie, a re-creation made with particular goals in mind. If you had different goals — different ideas about what the significant parts of movies were, different imagined use-cases — you might decompose differently. There is more than one way to tear apart content. (emphasis added)
In other words, the value of a reductionist analysis of a piece of work is not just in understanding the parts and how they fit, but in understanding the choices that led to that particular decomposition.

I think there are important lessons here for anyone involved in the creation and evaluation of new work. In particular:

Reading: While this is mostly advice for students, it applies whenever you're reading unfamiliar material. The particular form of the paper -- how the proofs are structured, how the system is built, or how the algorithm components work -- is a choice made by the authors and should not be left unexamined or unquestioned. All too often a student will read a paper as a factual news report, rather than reading it as a specific interpretation of a problem/algorithm/theorem that could lend itself to multiple interpretations (just a few days ago I was discussing some JL results with a colleague and realized that we had totally distinct and valid interpretations of some recent work in the area).

Reviewing: It's very easy (and common) to read a paper, understand the proofs, and then be completely underwhelmed by it: the dreaded "too simple" feeling that leads papers to get rejected from unnamed theory conferences. This is especially true when you're not familiar with an area, and don't realize that it was the choices the author(s) made that made the paper look simple. And so your assessment has to factor that choice in, rather than taking it for granted.

Writing/Presenting: Of course all of this impacts how you as a creator choose to present your work. There is not one way to tell a story (in writing or in a talk). But you do make choices about how to tell it. And so it's important to make those choices visible (either by explaining why they are needed, or why different choices don't work, or how they get around certain roadblocks) so that your work can receive a fair evaluation.

This can be excruciating, especially when (like many good papers) your work admits multiple interpretations, and you have to gamble on the right one to please the fickle and time-stretched reviewer. But be mindful of these choices in your work.

p.s On a separate note, it's intriguing to me how so many tools from the study of literature (narrative, contextual analysis, critical reading) show up in other forms of writing far removed from the humanities. This is yet another reason why I'm saddened (even though I'm on the "right" team) by the relentless focus on STEM in opposition to the liberal arts. It's a particularly virulent form of divide-and-conquer (the British colonial technique, not the algorithmic paradigm).

p.p.s Has it really been three months since I wrote anything ? I must be working !!

Thursday, November 14, 2013

The many stages of writing a paper, and how to close the deal.

[tl;dr] Producing a piece of research for publication has many stages, and each stage has different needs, requiring different ways of operating. Learning these stages is a key developmental step for a graduate student. In what follows, I describe this process.

Caveat: this is obviously customized to more theoretical-style work, although I'll talk about how experimental evaluation fits in, in the context of my work. So YMMV.

From my conversations with students (mine and others), I think this accurately describes how students think a paper gets written:

  1. Advisor produces problem miraculously from thin air. 
  2. Come up with solution.
  3. Write down solution
  4. Advisor makes annoying and mystifying edit requests on irrelevant introductory stuff, while throwing out long complicated proofs (or experiments) student has spent many hours sweating over.
  5. Make final edits and submit paper.
Most student figure out  how to do 2) , and eventually learn how to do 3) (which is itself a topic for another post). 5) is probably the first thing students learn how to do: fix typos, edit latex, and generally do yak-shaving.

But step 4) is perhaps the most mysterious part of the writing process for a new researcher, and the least structured. I call it "closing the deal" and it's really about going from a bag of results to an actual submittable paper. 

Let me elaborate.

1) Coming up with a problem.
    Of course coming up with a problem is the essence of the research process ("it's about the questions, not the answers", he shrieks). This takes experience and vision, and can often be changed by things you do in stage 4. I'll say no more about it here.

2) Solving a problem.
    This is the stage that everyone knows about. That's what we do, after all - solve problems ! This is where we drink lots of coffee, live Eye of the Tiger montages, get inspiration in our sleep, and so on. 

   It often happens that you don't exactly solve the problem you set out to attack, but you make many dents in it, solving special cases and variants. It's important to be flexible here, instead of banging your head against a wall head-on. At any rate, you either exit this stage of the project completely stuck, with a complete solution, or with a collection of results, ideas and conjectures surrounding the problem (the most typical case)

3) Writing it all down.
   Again, I could spend hours talking about this, and many people better than I have. It's a skill to learn in and of itself, and depends tremendously in the community you're in.

4) Closing, or getting to a submission.
    But this is the part that that's often the most critical, and the least understood. I call it "closing the deal": getting from 80% to 100% of a submission, and it requires a different kind of skill. The overarching message is this:
A paper tells a story, and you have to shape your results - their ordering, presentation, and even what you keep and what you leave out - in order to tell a consistent and clear story. 
(before people start howling, I'm not talking about leaving out results that contradict the story; that would be dishonest. I'm talking about selecting which story to tell from among the many that might present themselves)

So you have a bag of results centering around a problem you're trying to solve. If the story that emerges is: "here's a problem that's been open for 20 years and we solved it", then your story is relatively easy to tell. All you have to do is explain how, and using what tools. 

But in general, life isn't that easy. Your results probably give some insights into the hard core of the problem: what parts are trivial, what directions might be blocked off, and so on. 

Now you need to find/discover the story of your paper. You can't do this too early in the research process: you need to explore the landscape of the problem and prove some results first. But you shouldn't wait too long either: this stage can take time, especially if the story changes.

And the story will change. One way of thinking about what you need for a conference submission is a relatively tight, compelling and interesting story. While the loose ends and unexplored directions are probably the thing most interesting to you and your research, they are best left to a conclusions section rather than the main body. What the body should contain is a well-thought out march through what you have discovered and what it says about the problem you're solving. In doing so, you will find yourself making decisions about what to keep, and what to leave out, and how to order what you keep. 

And so, speculations need to be made into concrete claims or triaged. Experiments need to be run till they tell a definite story. Introductions need to be made coherent with the rest of the paper. There's also an element of bolt-tightening: making the bounds as tight as possible, stating claims as generally as makes sense for the overarching story (if your story is about points in the plane, then stating some claims in a general metric space might not always make sense). 

And all of this has to be done to serve the overarching story that will make the most compelling paper possible. The story can change as new results come in, or expand, or sometimes even die, (but this latter is rare). But there is this constant drumbeat of "am I getting closer to a submission with a nice story with each step".

Telling a good story is important. For someone to appreciate your paper, cite it, or even talk about it (whether it's accepted, or on the arxiv) they have to be willing to read it and retain its results. And they'll be able to do that if it tells a clear story, which is not just a union of results. 

Tuesday, November 05, 2013

SODA 2014 travel awards and other news

Via Cliff Stein and Kirsten Wilden:

The SIAM Symposium on Discrete Algorithms (SODA14) will be held January 5-7, 2014 at the Hilton Portland & Executive Tower in Portland, Oregon, USA. Algorithm Engineering and Experiments (ALENEX14) and Analytic Algorithmics and Combinatorics (ANALCO14) will be co-located with the conference on January 5 and 6, respectively.
 The deadline for students to apply for travel support is approaching!   The NSF, Google, IBM Research, and Microsoft Corporation have provided generous travel support for students interested in attending SODA14 or its associated meetings, ALENEX14 and ANALCO14. Application materials and a letter of recommendation from your advisor are due by November 15. Please visit http://www.siam.org/meetings/da14/tsupport.php for detailed funding information and application procedures.

Pre-registration for all three meetings is also available at http://www.siam.org/meetings/da14/reginfo.php.

Additional conference information is available at the following websites:
SODA14:  http://www.siam.org/meetings/da14/ANALCO14: http://www.siam.org/meetings/analco14/ALENEX14: http://www.siam.org/meetings/alenex14/

Sunday, October 27, 2013

FOCS Reception sing-along

Tomorrow night at 7:30 (before the FOCS business meeting at 9), the Positive Eigenvalues will be playing a live set for the entertainment of  FOCSers. 

Who are the Positive Eigenvalues, you might ask ? Well, you'll have to come and hear us to find out :). Two of the songs we're playing are compositions by our resident philosopher/graphic novelist/keyboardist/composer/complexity theorist, Christos Papadimitriou.

The first is a riff off the Dylan song "Man gave names to all the animals", with the same tune but different lyrics. If you're so inspired, you're encouraged to sing along to the chorus (which repeats after each verse). It goes like this:
Chorus: 
Theorists gave names to all the classes
in the beginning, in the beginning
Theorists gave names to all the classes
in the beginning long time ago 

Verse 1:
They saw a woman slim and tall
forging steadily to her goal
she went by fast but that's no crime
uh I think I'll call her PTIME

Verse 2:
They saw a kid who soldiered on
he got no rest from dusk to dawn
he kept sweating in the same place
uh I think I'll call him PSPACE

Verse 3:
They saw a blind man comb his shack
to find his walkstick in the black
but once he found it he could see
uh I think I'll call him NP

Verse 4:
They saw a boy who walked and walked all night
never veered to the left or right
was kind of slow but not that bad
uh I think I'll call him PPAD

Verse 5:
There was a beast and on its back
it carried Heisenberg and Dirac
it was as weird as a beast can be
uh...
For more on the tailed off line at the end, see the wikipedia entry.

The second song is an original composition by Christos in rock ballad/power rock mode. The lyrics speak poignantly about the life of a theoretician:
In Theory
Verse
Think of a carpenter of sorts
he has the flu he has the blues
He burns his oil every night
all night frustrated and confused

Bridge
And worst of all he can't complain
In theory his job is plain  (twice)

Chorus
Build something sturdy and beautiful and useful
He's always short in one goal
He juggles true with elegant and useful
and he keeps dropping one ball

Verse 2
His buddies like him alright
except they love to criticize
They go and take his stuff apart
with clever words with clever eyes

Verse 3
Some nights a girl comes to his shop
to sip his tea learn something raw
his foggy mind his tangled soul
want her to stay but let her go

Thursday, October 17, 2013

Searching randomly for needles.

Suppose you're given a large set of objects $X$, and you know that some subset $I$ is "interesting". A particular example that hits close to (my regular) home is in bug-testing: $X$ is the set of possible inputs to a program, and $I$ is the set of inputs that generate bugs (this is the downside of talking to +John Regehr too much). We'll assume that if you're given a candidate object, you can check easily if it's interesting or not (for example, by running the program)

You'd like to find the interesting items, so you consult an expert (in our running example, maybe it's a method to generate inputs that test certain kinds of bugs). The expert produces items that it thinks are interesting. But experts have biases: maybe your expert only cares about certain kinds of interesting items.

So you ask multiple experts, in the hope that their biases are different, and that together they can cover the space of objects. But you don't know anything about their biases except what you can learn from repeatedly asking them for candidate objects.

What's your strategy for asking questions so that at any stage (say after asking $N$ questions), you've found the optimal number of interesting items ?

This was the topic of a talk by +Sebastien Bubeck at the AMPLab in Berkeley on Tuesday, based on this paper.  A key idea in the algorithm design is to make use of estimators of "things I haven't seen yet", or the famous Good-Turing estimator (which your humble blogger wrote about many æons ago). Here's how it works.

Formally, let us assume that each "expert" $i$ is a distribution $P_i$ over $X$. At each step, the algorithm will determine some $i$, and ask it for a random draw from $P_i$. Suppose we knew the fraction of items that $i$ had not seen yet. Then a simple greedy strategy would be to pick the $i$ that had the largest value of this "not-yet-seen" quantity. That's all well and good, as long as we know the fraction of items not yet seen.

Here's where the G-T estimator comes in. What it says is that if we're given samples from a distribution, and count the number of items in the sample that occurred exactly once, then this "frequency of frequency", divided by the number of samples, is a good estimate for the mass of items not yet seen. Moreover, it can be shown that this estimator has good concentration properties around the true answer.

So that's what the algorithm does. It maintains estimates (for each expert) of the mass not yet seen, and in each round picks the expert that maximizes this term, corrected by an adjustment coming from the tail of the concentration bound.

The algorithm is really simple, and elegant. The question is, how well does it do ? And now things get a little harder. The above ideal greedy strategy is optimal as long as the supports of the experts are disjoint. Under the same assumption (and some other technical ones), it can be shown that the expected difference between the number of items found by the algorithm and the number found by the ideal greedy algorithm is $O(\sqrt{Kt \log t})$ where $K$ is the number of experts and $t$ is the current time step.

It's not clear how to extend these bounds to the case when supports can overlap (or rather, it's not clear to me :)), but the authors show that the algorithm works quite well in practice even when this assumption is broken, which is encouraging.

Wednesday, October 16, 2013

Progressively complex representations for graphs

After NIPS last year, I had posted a note on the evolution of data models and how we think about the "shape" of data. In brief, we have increasingly complex ways of thinking about the (geometric) shape of data that carefully balance the need for expressivity and the ability to determine the parameters of the representation efficiently.

There's a basic fact of data analysis that you come up against once you start playing with data. Either you endow the space with a geometry, or you endow it with a graph structure (and of course, nowadays you might throw in a spherical cow or two). And there are only a few ways to mix the representations (spectral methods being one such approach).

But as far as I know, there are no standard ways to create a layered representation of graphs to model increasing complexity and expressivity in a similarly balanced manner. There are of course an infinite number of ways to parametrize graphs by quantities that capture increasing complexity (treewidth, connectivity, expansion, induced metric structure, and so on). But I don't know of any established and standard ways to model families of graphs with increasing complexity that capture data patterns of interest.

One of the things that I've been tasked with (along with Peter Richtarik and Han Liu) is to draft out a report on the activities at the big data program at Simons this semester. We're looking also at challenges in the theory of big data, and in my mind coming up with good models for graph structures that capture the intricacies of real data is one of them.

Wednesday, October 02, 2013

Call for tutorials at SIAM Data Mining

I'm the tutorials chair for the 2014  SIAM conference on data mining (SDM) (for readers not aware of the data mining landscape, SDM is a SODA-style data mining conference run by SIAM - i.e it's a CS-style venue with peer-reviewed papers, rather than a math-style conference like SIAM discrete math). SDM is one of the major venues for data mining research, especially the more statistically focused kind. It will be held in Philadelphia between Apr 24-26, 2014.

SDM runs 4-5 tutorials each year on various aspects of data mining (ranging from theory/algorithms to specific application areas). I'm personally very interested in encouraging submissions from people in the theory community working with data who might want to share their expertise about new methods/techniques from theoryCS land with the larger data analysis community.

The deadline is Oct 13, and all you need is a few pages describing the tutorial content, target audience, and some sample material (more details here). If you have an idea and are not sure whether it will fit, feel free to email me directly as well.

Disqus for The Geomblog